Start without overlap
Shrinking the bodies first creates a separated scene, even when the original overlaps are severe.
ACM Transactions on Graphics (SIGGRAPH Asia 2026)
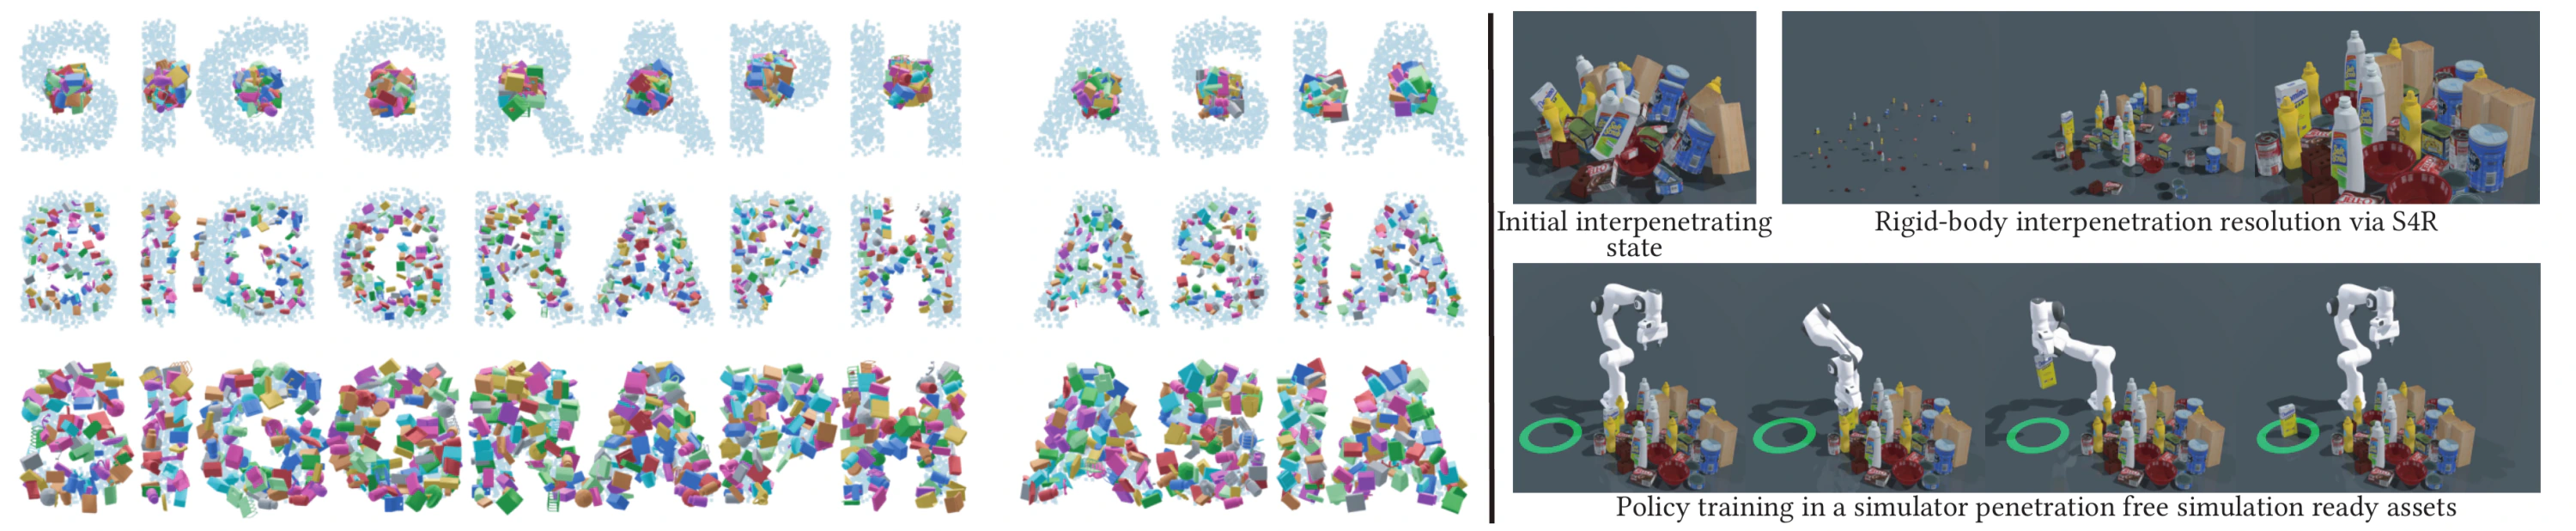
A 20-second overview of S4R.
Removing static rigid-body overlaps by shrinking and restoring objects.
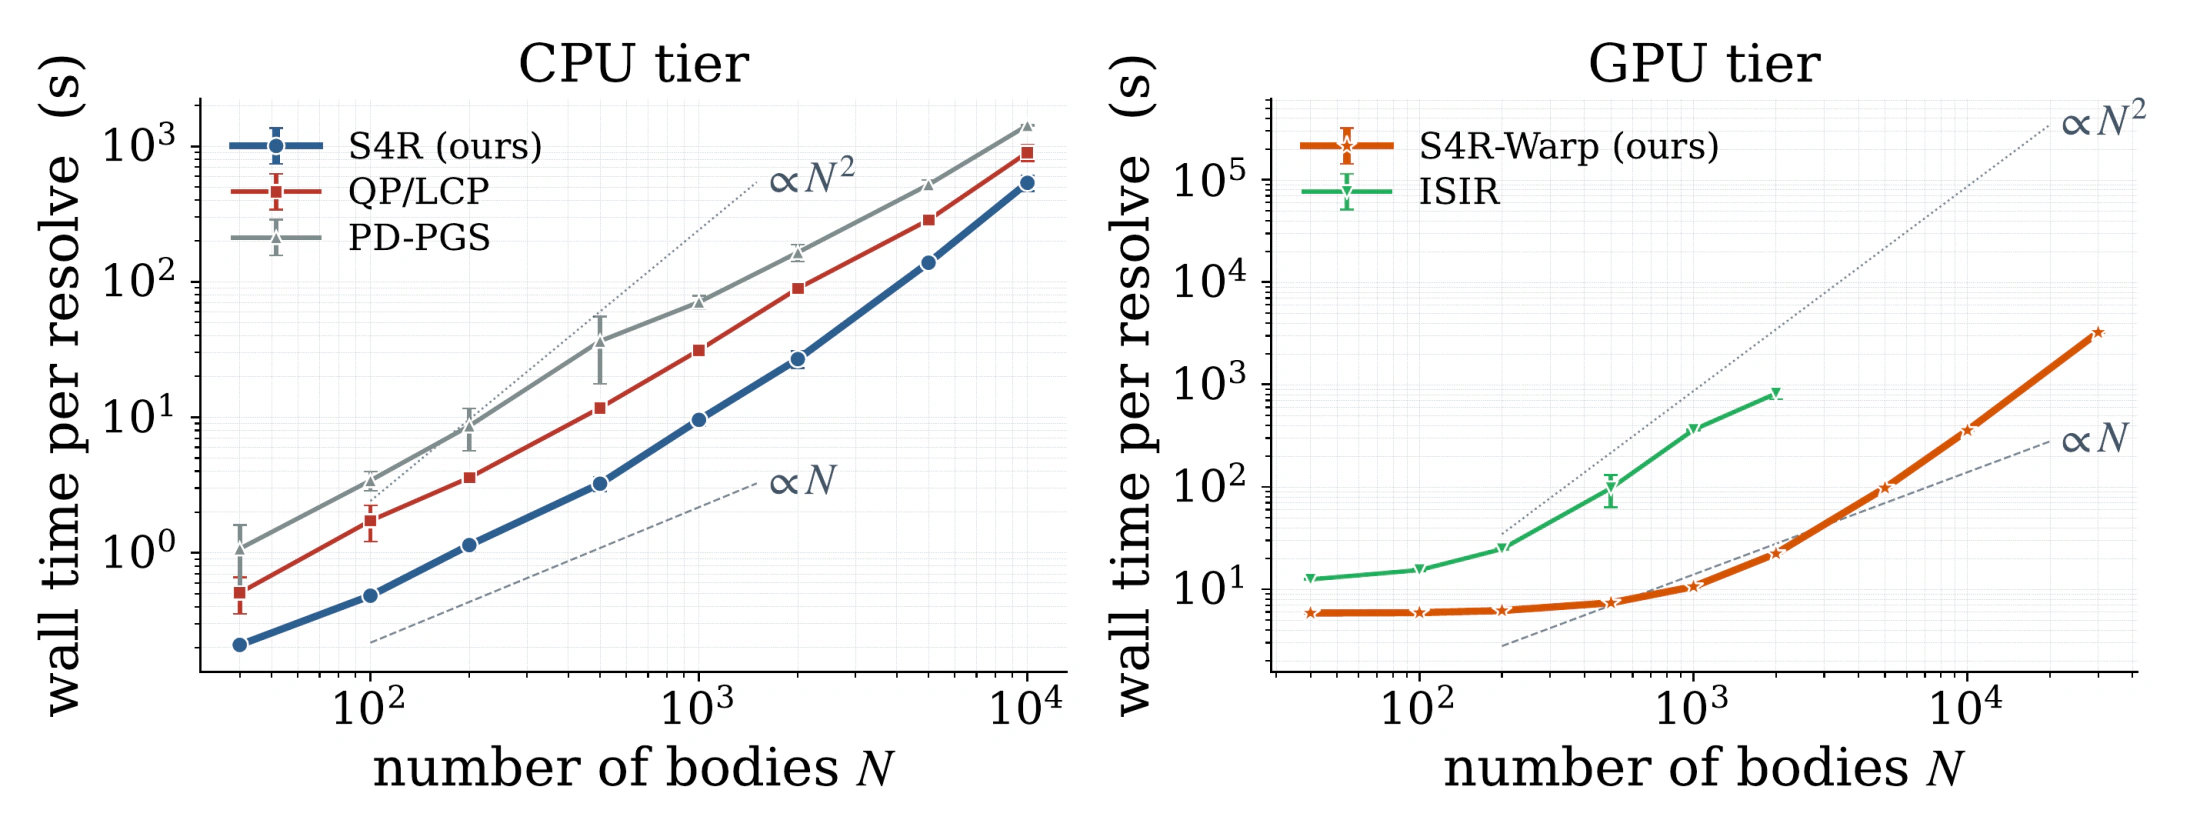
Rigid-body interpenetration frequently occurs in procedurally assembled and generated scenes and must be removed before downstream applications such as physical simulation. We present S4R (Scaling for Rigid-Body Interpenetration Resolution), a scale-continuation method for static interpenetration repair. S4R first uniformly shrinks each body about a fixed reference center to a small initial scale, at which the layout is penetration-free, and then restores full scale through a sequence of minimum-norm convex contact quadratic programs (QPs) that target the linearized separation margin during continuation. Resolution thereby replaces one deep correction with a sequence of shallow-contact subproblems. A conservative scale-event bound and frozen-witness gap predictions cut the number of exact mesh queries; the continuation then ends with a full-scale evaluator check and bounded tail refinement. We evaluate S4R on Kubric [Greff et al. 2022], HY3D-Bench [Team Hunyuan3D et al. 2026], and Thingi10K [Zhou and Jacobson 2016] using a shared mesh-level evaluator and a unified per-scene timing protocol. In the main comparisons on all three benchmarks, up to 5000 bodies, S4R reaches zero reported penetration with displacement that stays small and nearly independent of scene size, and at the lowest wall time within each hardware tier among the compared methods. A GPU implementation extends these results to large-scale scenes. Our code and data can be found on our project page: https://frank-zy-dou.github.io/projects/S4R/index.html.
Separate objects at a small scale, then restore their size in controlled steps.
S4R first shrinks every body until the scene has no overlap. It then restores the bodies to full size in small steps. At each step, an optimization moves only the bodies that are touching and keeps the movement as small as possible. Exact mesh checks verify the result and remove any remaining overlap at full size.
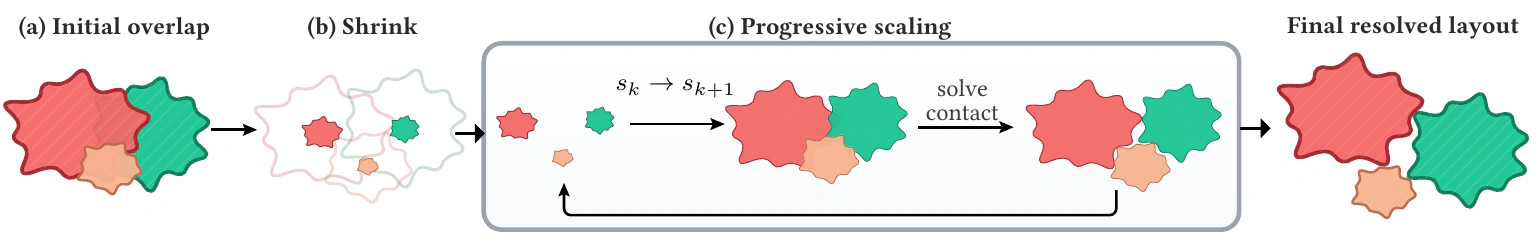
Shrinking the bodies first creates a separated scene, even when the original overlaps are severe.
Each step increases the body size and moves touching objects only as much as needed to keep them apart.
Fast distance estimates reduce repeated collision checks, while an exact mesh check verifies the full-size result.
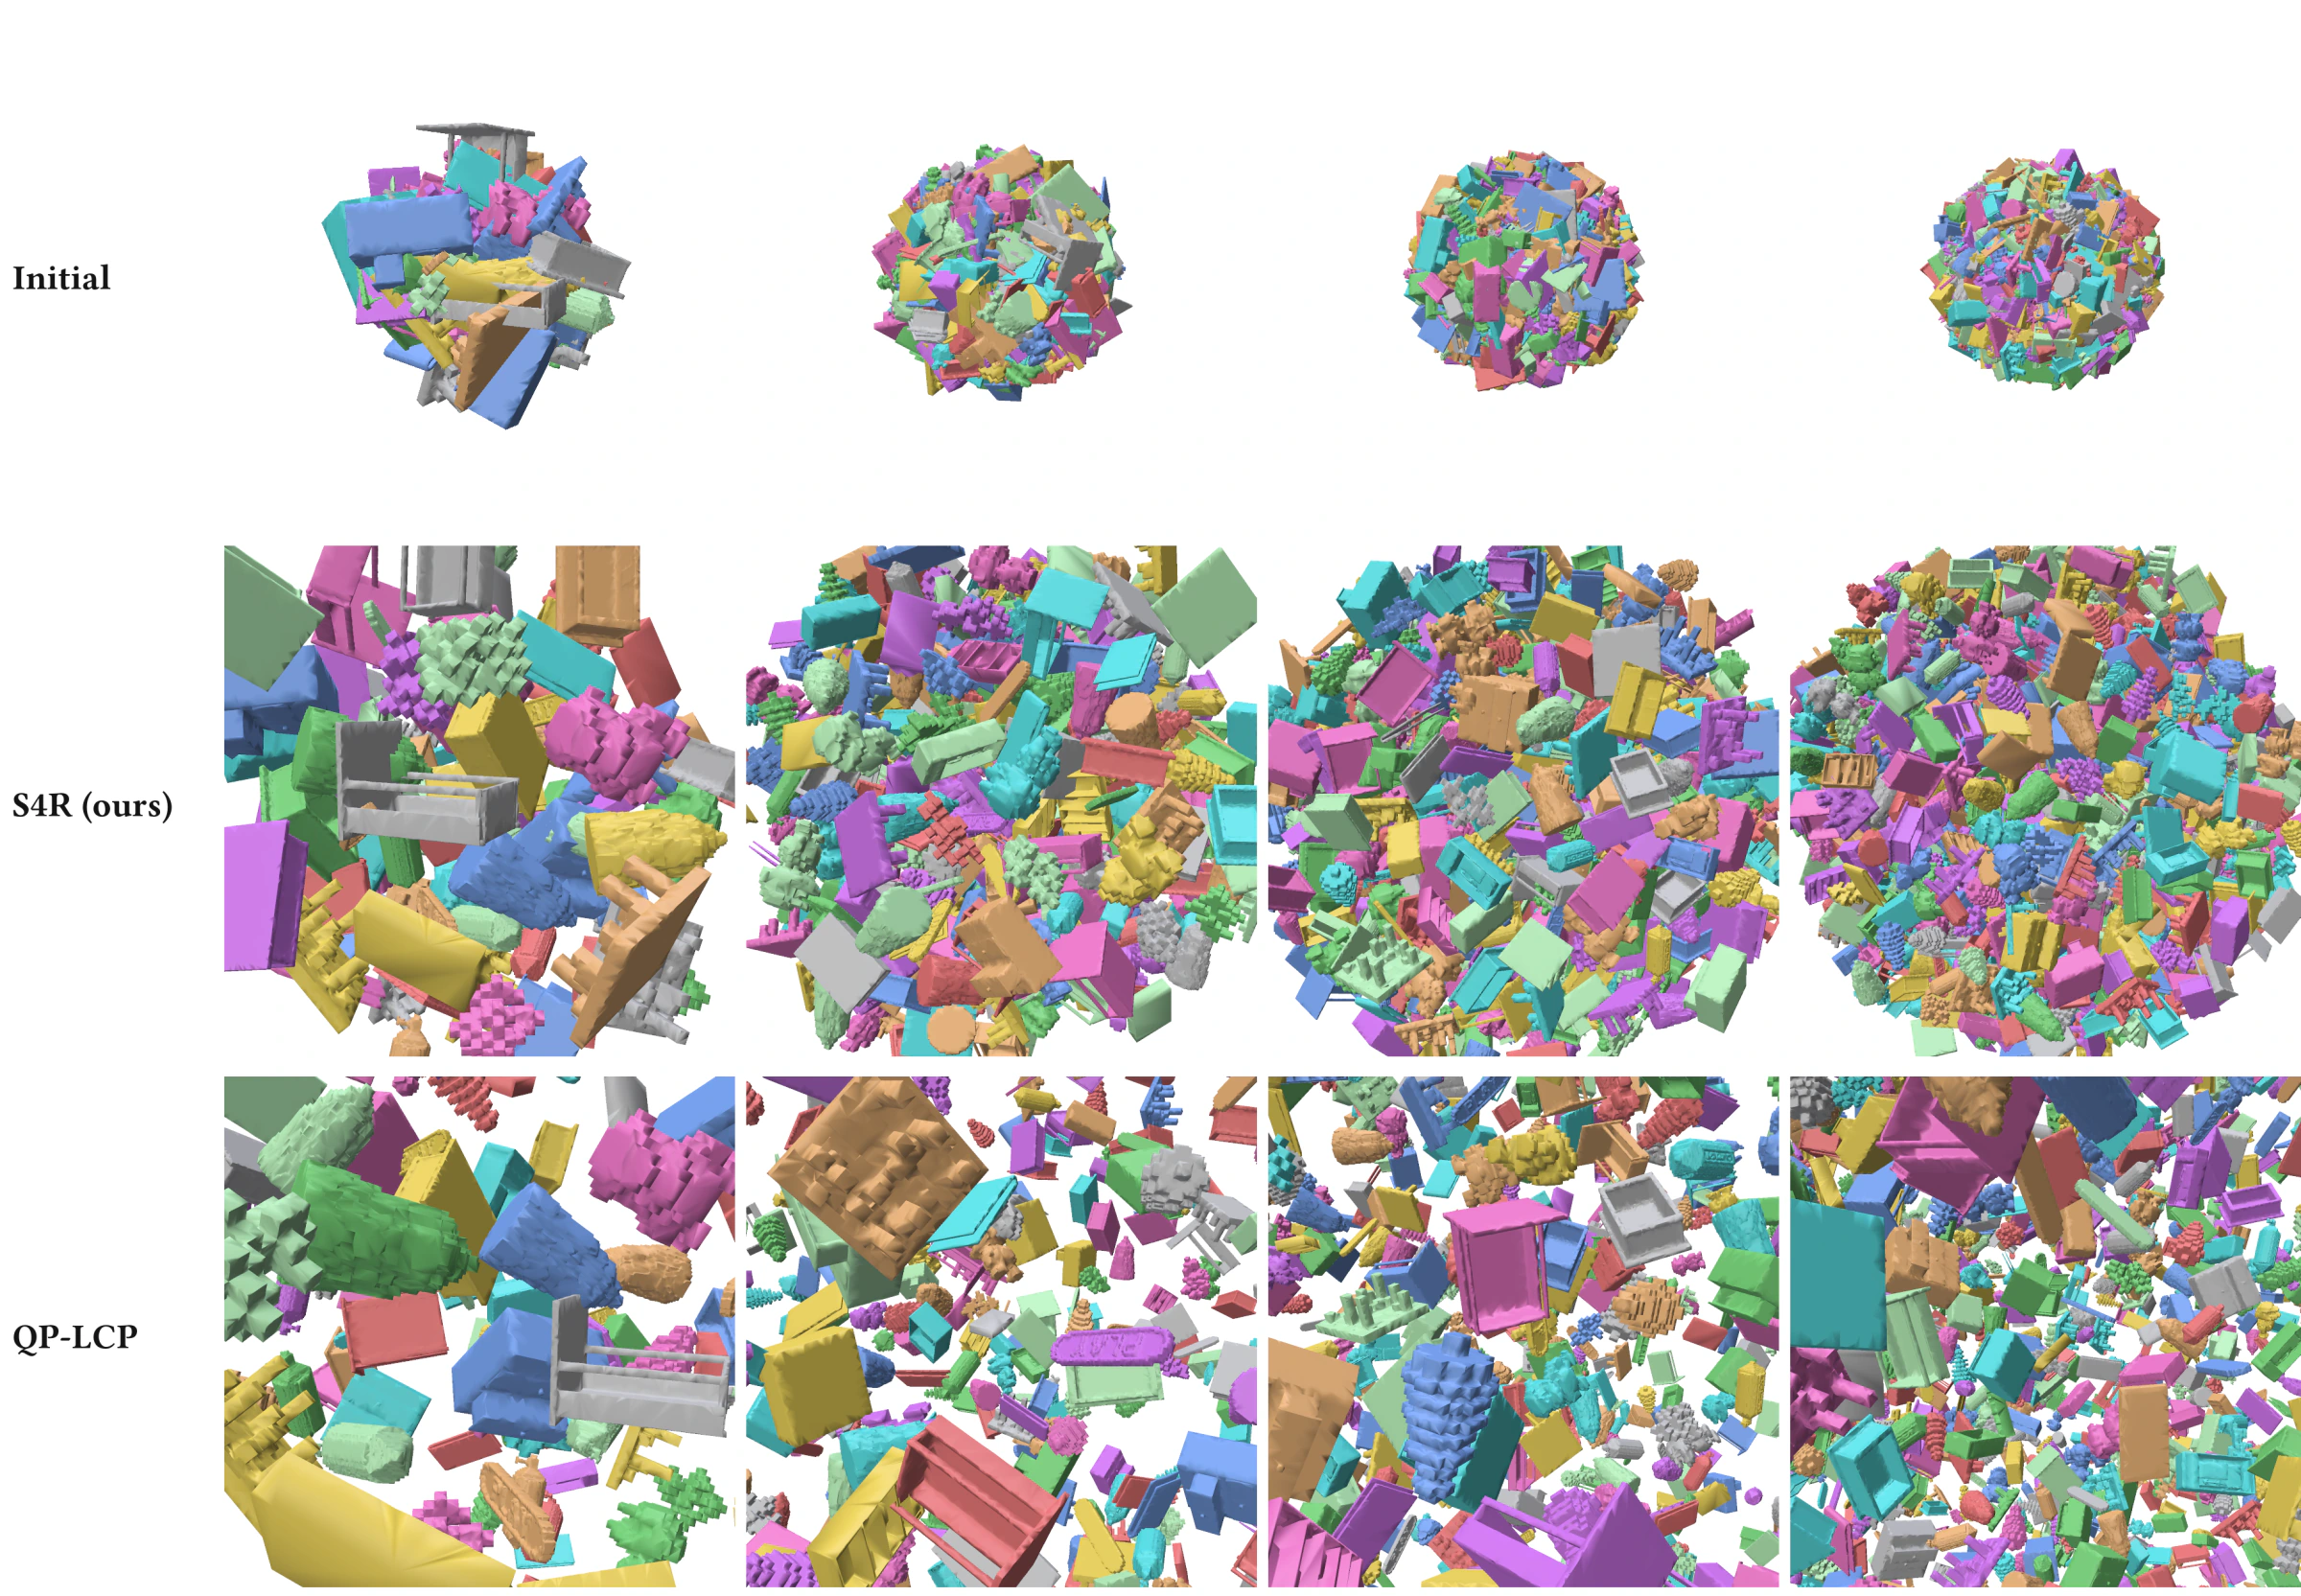
Every method uses the same final collision check and is timed from scene setup to completion.
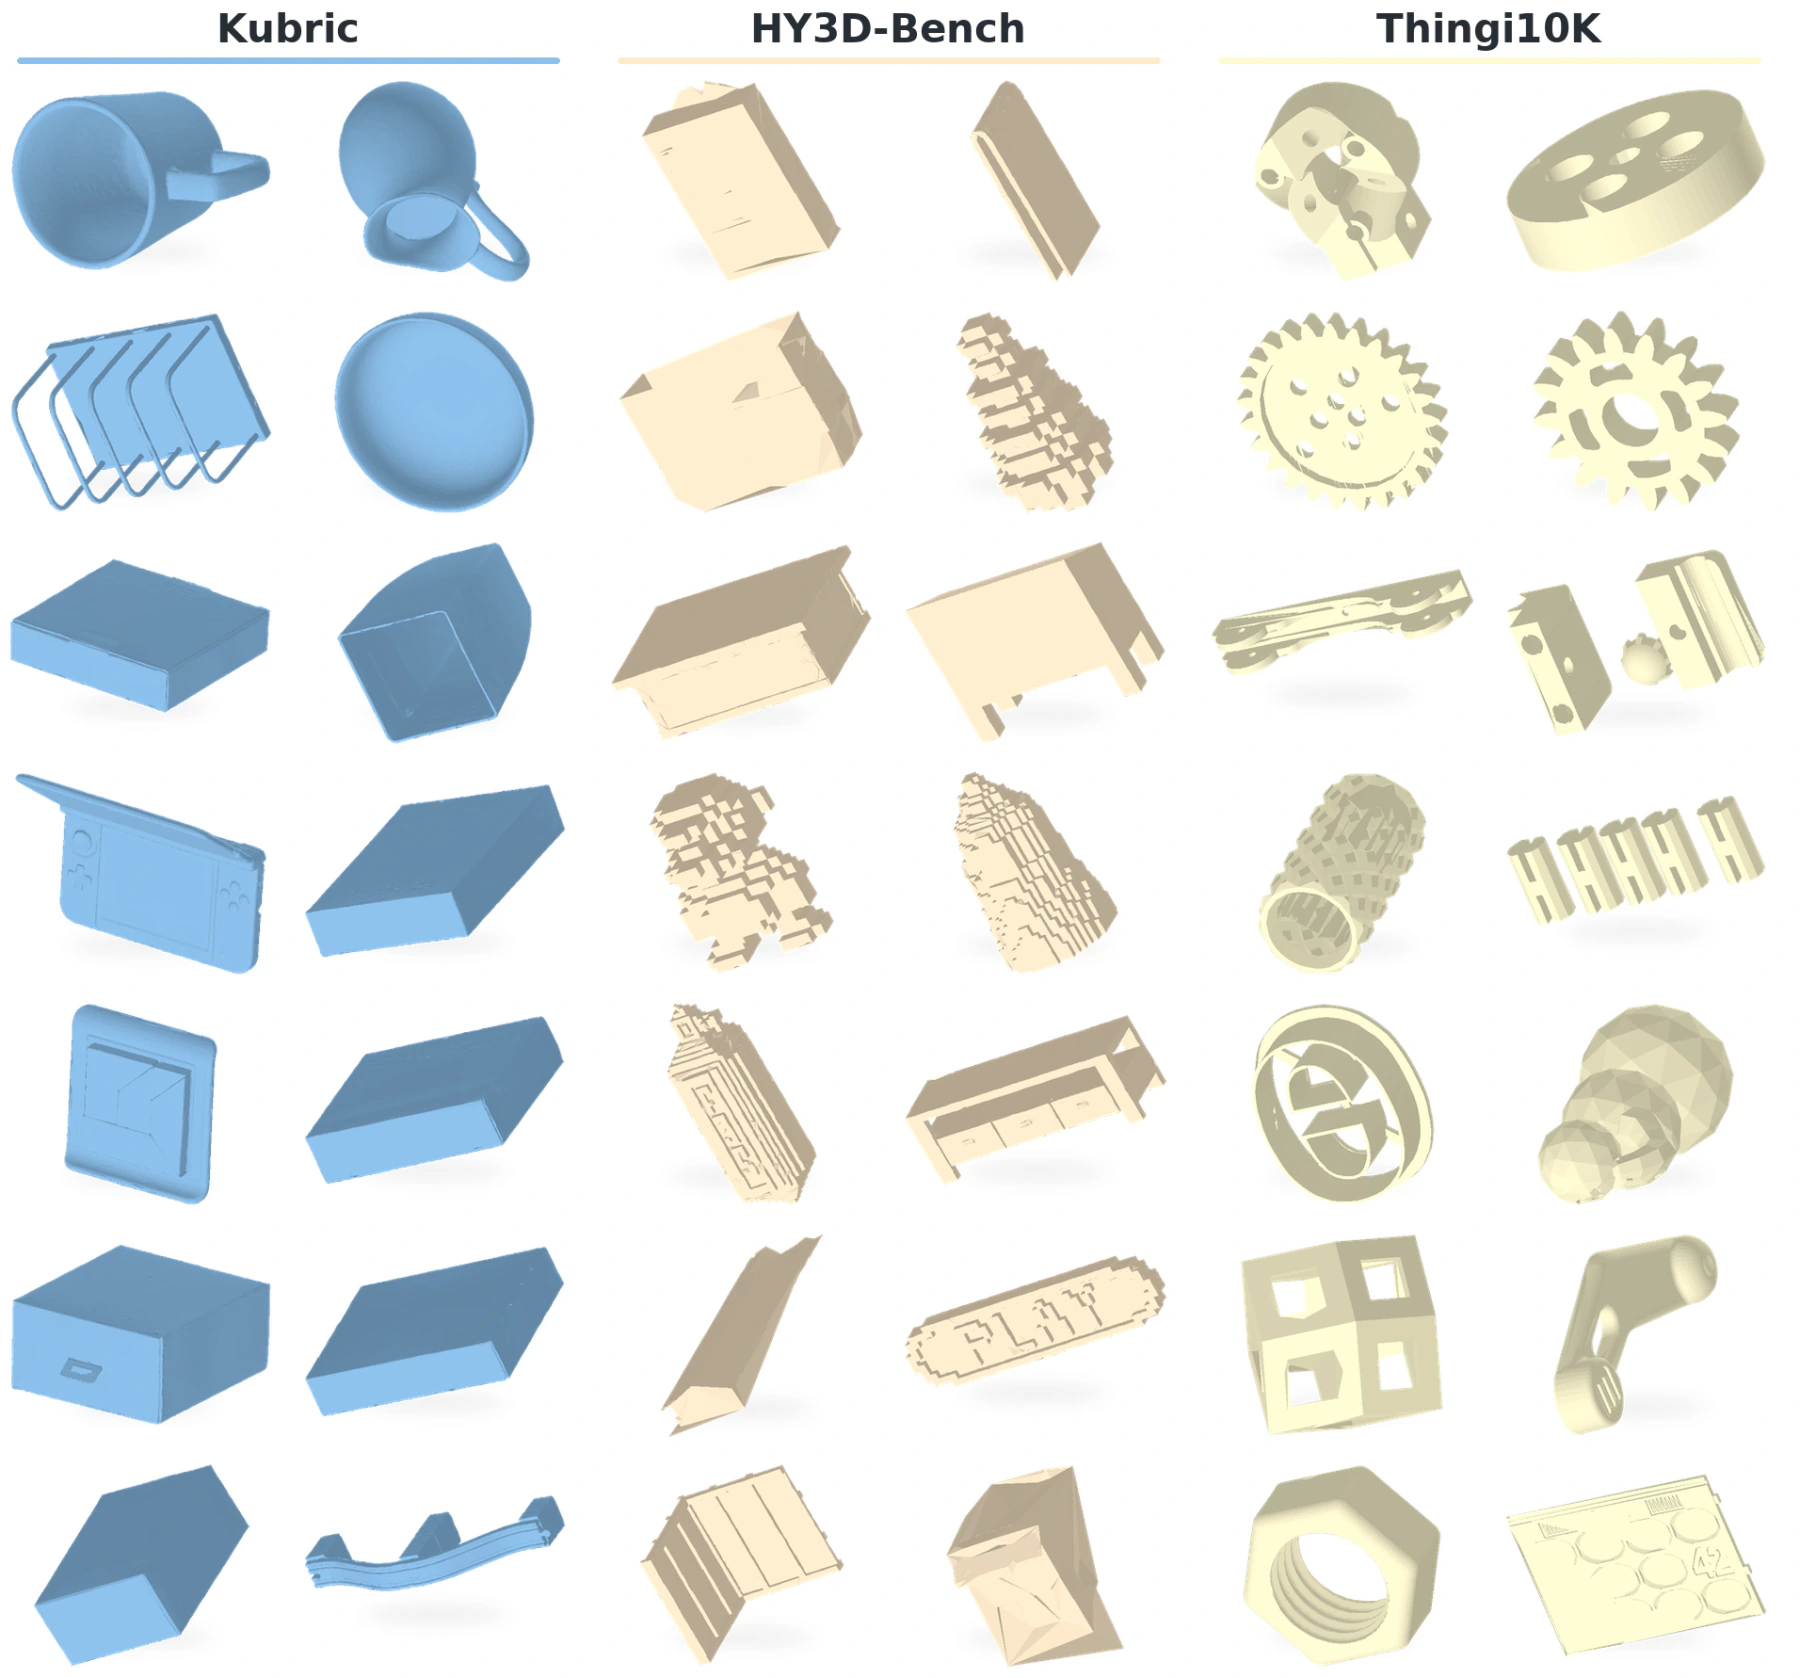
Evaluation geometry. The experiments cover household objects, generated 3D assets, and artist-created models for 3D printing.
| Method | N = 40 | N = 100 | ||||
|---|---|---|---|---|---|---|
| Pen. (pairs) | RMSD (scene units) | Time (s) | Pen. (pairs) | RMSD (scene units) | Time (s) | |
| CPU methods (one 14-core socket) | ||||||
| AVBD-OBB (tuned)♮ | 0 | 1.33 | 2.2 | 0 | 2.34 | 8.0 |
| AVBD-OBB (official)♭ | 02/3 | 4.46 | 1.2 | 0 | 1.15 | 3.3 |
| Drake-Ipopt (hull)† | 0 | 0.022 | 597 | 01/3 | 0.0251/3 | 6,5181/3 |
| Drake-SNOPT (hull)† | 0 | 0.023 | 22.6 | 0 | 0.025 | 553 |
| QP/LCP | 0 | 0.038 | 0.5 | 0 | 0.039 | 1.7 |
| PD-PGS | 0 | 0.028 | 1.1 | 0 | 0.027 | 3.4 |
| Soft-Pen. | 0 | 0.032 | 19.6 | 0 | 0.034 | 114 |
| S4R (CPU, ours) | 0 | 0.036 | 0.2 | 0 | 0.035 | 0.4 |
| GPU methods (1× RTX 2080 Ti) | ||||||
| ISIR | 0 | 0.175 | 14 | 0 | 0.175 | 14 |
| S4R-Warp (ours) | 0 | 0.035 | 1.5 | 0 | 0.035 | 1.6 |
Table 1. Main comparison on Kubric. Three-seed means at N = 40 and 100. Pen. counts negative-score body pairs under the shared mesh evaluator; RMSD measures reference-center displacement. Within each hardware tier, bold marks the best value and underline marks the runner-up; ties at zero penetration are all bold, and the two-method GPU tier marks only the best. Superscript fractions report completed seeds. † Drake uses a tightened bound and a 7,200 s budget. ♮ and ♭ denote the tuned and released AVBD-OBB configurations.
| N | CPU (single socket) | GPU (1× RTX 2080 Ti) | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| S4R (ours) | QP/LCP | PD-PGS | S4R-Warp (ours) | ISIR | ||||||
| RMSD | Time (s) | RMSD | Time (s) | RMSD | Time (s) | RMSD | Time (s) | RMSD | Time (s) | |
| 40 | 0.036 | 0.2 | 0.038 | 0.5 | 0.028 | 1.1 | 0.035 | 1.5 | 0.175 | 14 |
| 100 | 0.035 | 0.4 | 0.039 | 1.7 | 0.027 | 3.4 | 0.035 | 1.6 | 0.175 | 14 |
| 200 | 0.035 | 1.0 | 0.039 | 3.6 | 0.026 | 9.2 | 0.034 | 1.7 | 0.241 | 51 |
| 500 | 0.034 | 3.0 | 0.040 | 11.7 | 0.024 | 36.5 | 0.033 | 2.1 | 0.298 | 135 |
| 1,000 | 0.035 | 7.7 | 0.040 | 29.8 | 0.025 | 69.2 | 0.034 | 2.9 | 0.356 | 427 |
| 2,000 | 0.037 | 17.5 | 0.042 | 79.8 | 0.025 | 150 | 0.036 | 4.6 | 0.394 | 1,305 |
| 5,000 | 0.037 | 68.1 | 0.042 | 220 | 0.025 | 404 | 0.036 | 9.7 | 0.445‡ | 1,775‡ |
Table 2. Scaling on Kubric. Three-seed means with setup-and-solve time. Within each hardware tier, bold marks the best RMSD and time per row and underline marks the runner-up; the two-method GPU tier marks only the best. Pen. is omitted because every displayed result reports zero penetration except the marked cell. ‡ ISIR stops at its per-seed budget at N = 5,000 with 39 residual pairs on average.
| Dataset | Method | N = 500 | N = 1,000 | N = 2,000 | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Pen. | RMSD | Time (s) | Pen. | RMSD | Time (s) | Pen. | RMSD | Time (s) | ||
| HY3D-Bench | S4R | 0 | 0.021 | 5.2 | 0 | 0.020 | 10.2 | 0 | 0.021 | 22.2 |
| QP/LCP | 0 | 0.022 | 13.2 | 0 | 0.022 | 31.9 | 0 | 0.022 | 65.4 | |
| PD-PGS | 0 | 0.013 | 28.1 | 0 | 0.013 | 73.3 | 0 | 0.013 | 172 | |
| AVBD-OBB | 8.7 | 1.123 | 70 | 46.7 | 0.935 | 210 | 104.7 | 0.935 | 730 | |
| ISIR | 0 | 0.196 | 226 | 0.3 | 0.197 | 949 | 0.3 | 0.233 | 1,472 | |
| Thingi10K | S4R | 0 | 0.025 | 4.5 | 0 | 0.026 | 8.7 | 0 | 0.026 | 21.4 |
| QP/LCP | 0 | 0.026 | 14.3 | 0 | 0.027 | 32.7 | 0 | 0.028 | 72.4 | |
| PD-PGS | 0 | 0.016 | 43.1 | 0 | 0.017 | 112 | 0 | 0.017 | 250 | |
| AVBD-OBB | 14.0 | 1.332 | 72 | 42.3 | 1.265 | 221 | 134.0 | 1.234 | 872 | |
| ISIR | 0 | 0.305 | 230 | 0.3 | 0.318 | 929 | 0.3 | 0.348 | 1,471 | |
Table 3. Cross-dataset comparison. Three-seed means. S4R, QP/LCP, and PD-PGS share FCL-based mesh queries; AVBD-OBB keeps its OBB proxies; ISIR runs in the GPU tier and is listed for completeness. Within each dataset, bold marks the best value and underline marks the runner-up; ties at zero penetration are all bold. AVBD-OBB reports mesh-level scores for poses produced with OBB collision proxies.
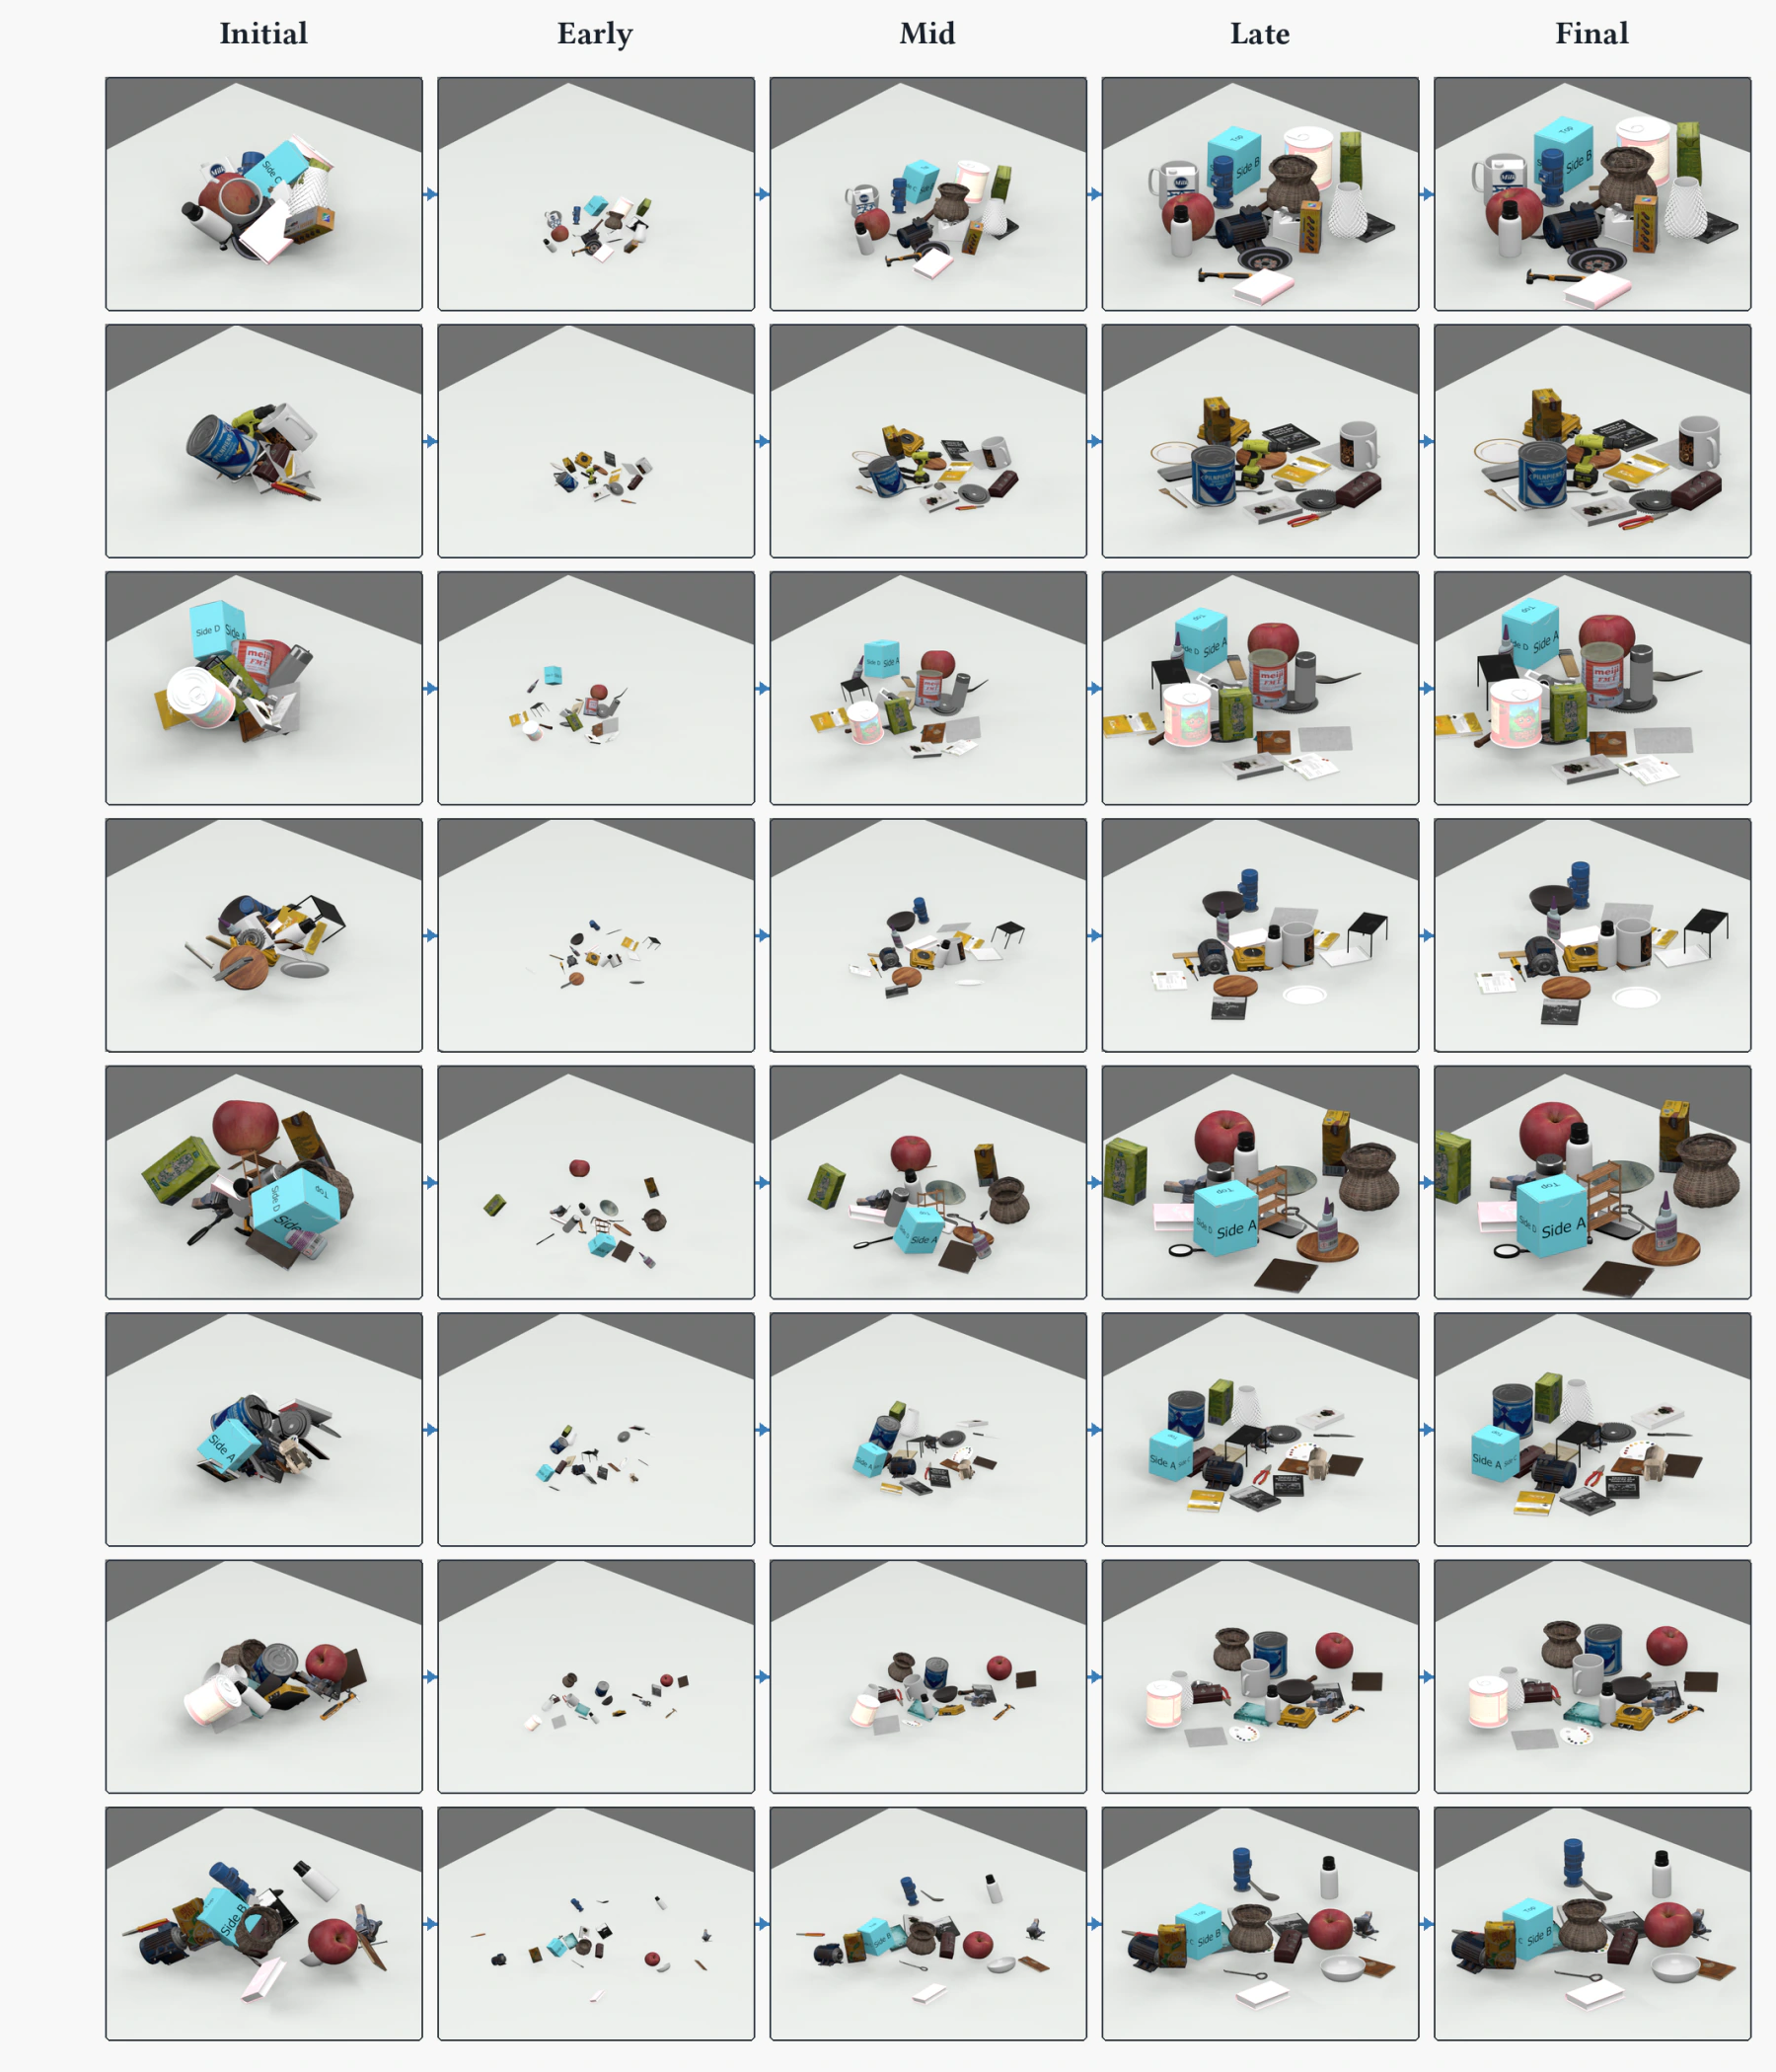
Each scene is shown from its initial overlap through intermediate sizes to the checked full-size result.
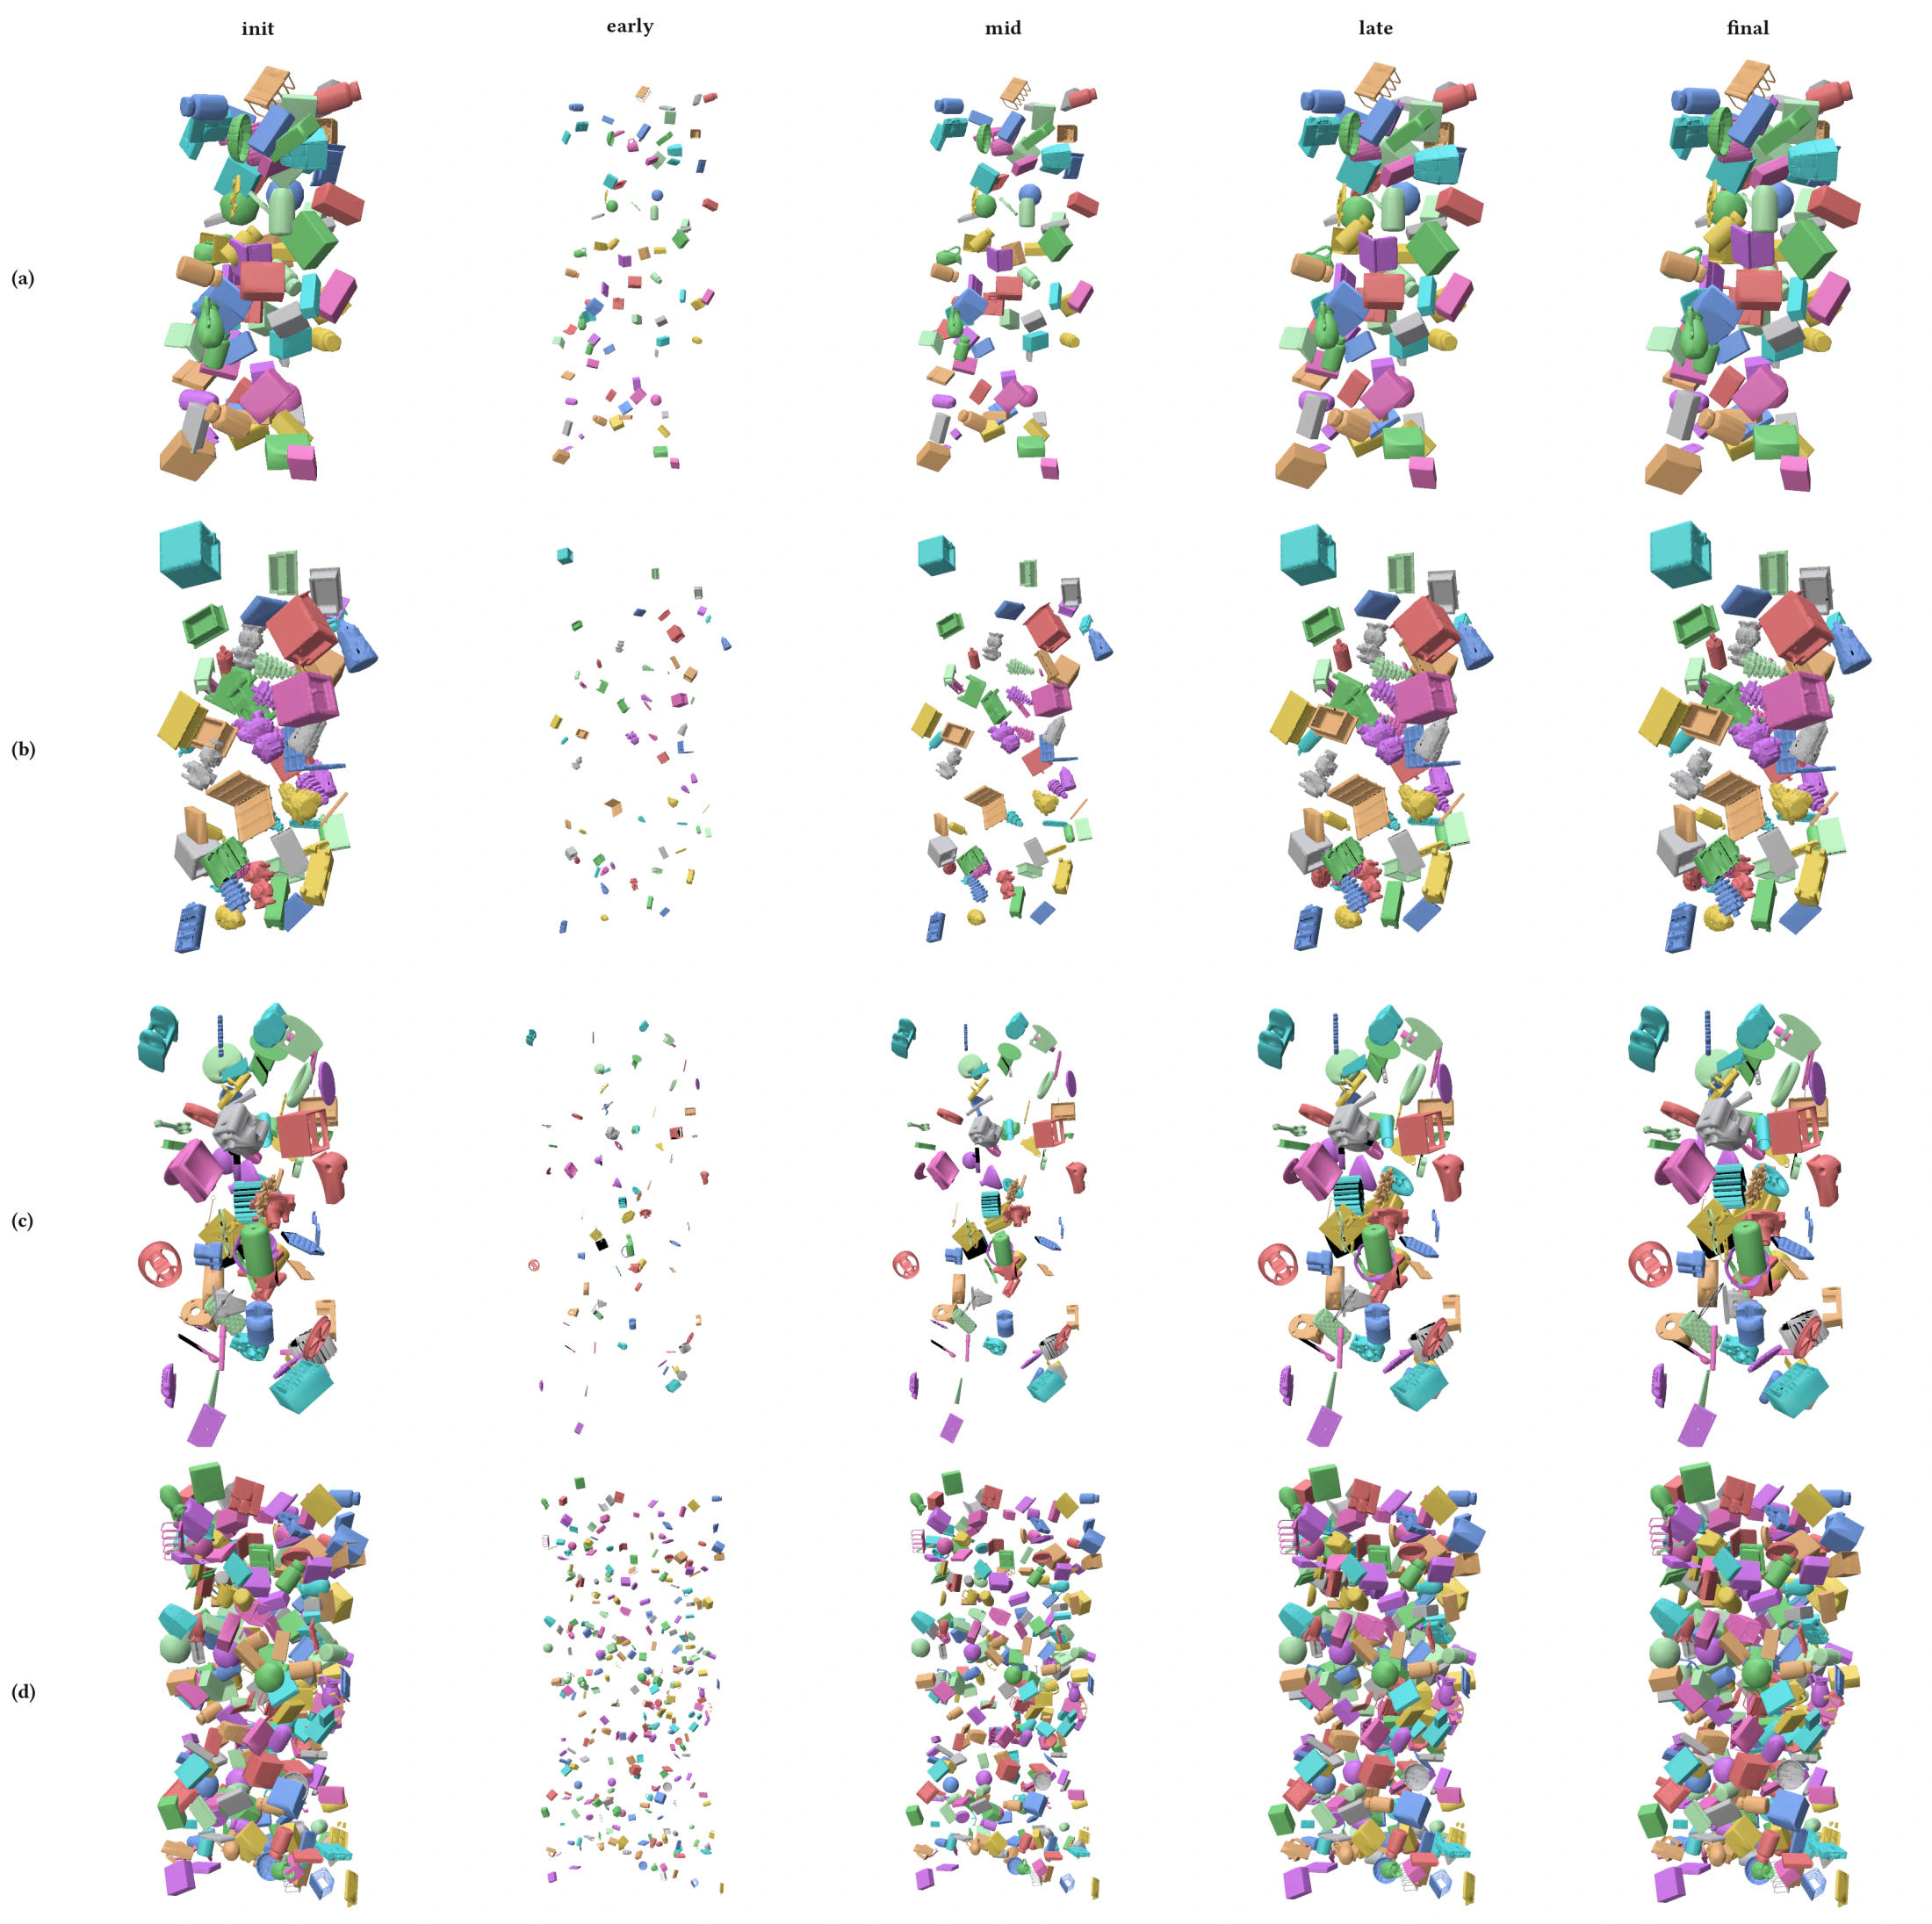
The main experiments move objects without rotating them. An optional version also allows small rotations. On the main benchmark, rotation reduces how far the objects need to move by about 13%, but it requires more collision checks and takes about fifteen times longer (Table 4). In the eight-seed packing study the reduction is 9–10% at 2.4–4.8 times the run time (Table 5).
| N | Method | Pen. (pairs) | RMSD | Time (s) |
|---|---|---|---|---|
| 40 | 3-DOF (translation only) | 0 | 0.036 | 0.16 |
| 6-DOF (translation + rotation) | 0 | 0.031 | 2.4 |
Table 4. 6-DOF versus translation-only QP on Kubric. Three-seed mean at N = 40. Rotation lowers RMSD by about 13% on these layouts but adds approximately 15× wall-time overhead.
| Spawn | 3-DOF (RMSD / Time) | 6-DOF (RMSD / Time) | 6-DOF : 3-DOF |
|---|---|---|---|
| Tight | 0.0869 / 1.98 s | 0.0792 / 9.59 s | RMSD 0.91×, time 4.8× |
| Loose | 0.0290 / 1.53 s | 0.0262 / 3.68 s | RMSD 0.90×, time 2.4× |
Table 5. Rotation as a packing lever. Eight-seed means on Kubric at N = 40; every cell reports zero penetration. Tight spawns are 2.5× smaller per axis than the main-benchmark loose spawns. The 6-DOF variant lowers RMSD on all eight seeds at higher wall time.
Repair generated assets, prepare scenes for simulation, and edit separated layouts.
For tabletop scenes, S4R keeps every object on the same flat surface while allowing it to slide and rotate around the vertical axis. The final full-size arrangement is checked using the same meshes shown in the rendered results.
| Method | N | Init Pen. (pairs) | Final Pen. (pairs) | RMSD | Time (s) |
|---|---|---|---|---|---|
| S4R | 100 | 87 | 0 | 0.039 | 1.5 |
| 500 | 491 | 0 | 0.043 | 11.6 | |
| 1,000 | 1,031 | 0 | 0.047 | 26.5 | |
| QP/LCP | 100 | 87 | 0 | 0.041 | 4.1 |
| 500 | 491 | 0 | 0.051 | 43.1 | |
| 1,000 | 1,031 | 0 | 0.051 | 105 | |
| PD-PGS | 100 | 87 | 0 | 0.028 | 16.8 |
| 500 | 491 | 0 | 0.031 | 123 | |
| 1,000 | 1,031 | 0 | 0.032 | 348 |
Table 6. Synthetic asset layout repair. Three-seed averages on the five-mesh solver-usable subset of the 88-asset pool. All methods use the same scenes and reach zero final penetration. S4R is fastest at every N, with RMSD below QP/LCP and above PD-PGS. Bold marks the best value and underline marks the runner-up; the penetration columns tie everywhere and are left unmarked.
Large overlaps can make simulated objects shoot apart or prevent a physics engine from starting. S4R provides overlap-free starting positions for MuJoCo, PyBullet, and Isaac Gym. In the paper experiments, the original YCB scenes eject objects, while the scenes repaired by S4R remain stable.
| Engine | Raw scene (m/s) | After S4R (m/s) |
|---|---|---|
| MuJoCo 3.10 | 7.8 | 0.000 |
| PyBullet 3.2.7 | 12.5 | 0.001 |
| Isaac Gym (PhysX) | 230.6 | 0.000 |
Rigid-body engines on an interpenetrating scene. Peak body speed over a one-second rollout from an interpenetrating YCB layout and from the same layout after S4R. Values are three-seed means for 50 bodies with gravity disabled, so the measured motion comes from contact response alone.
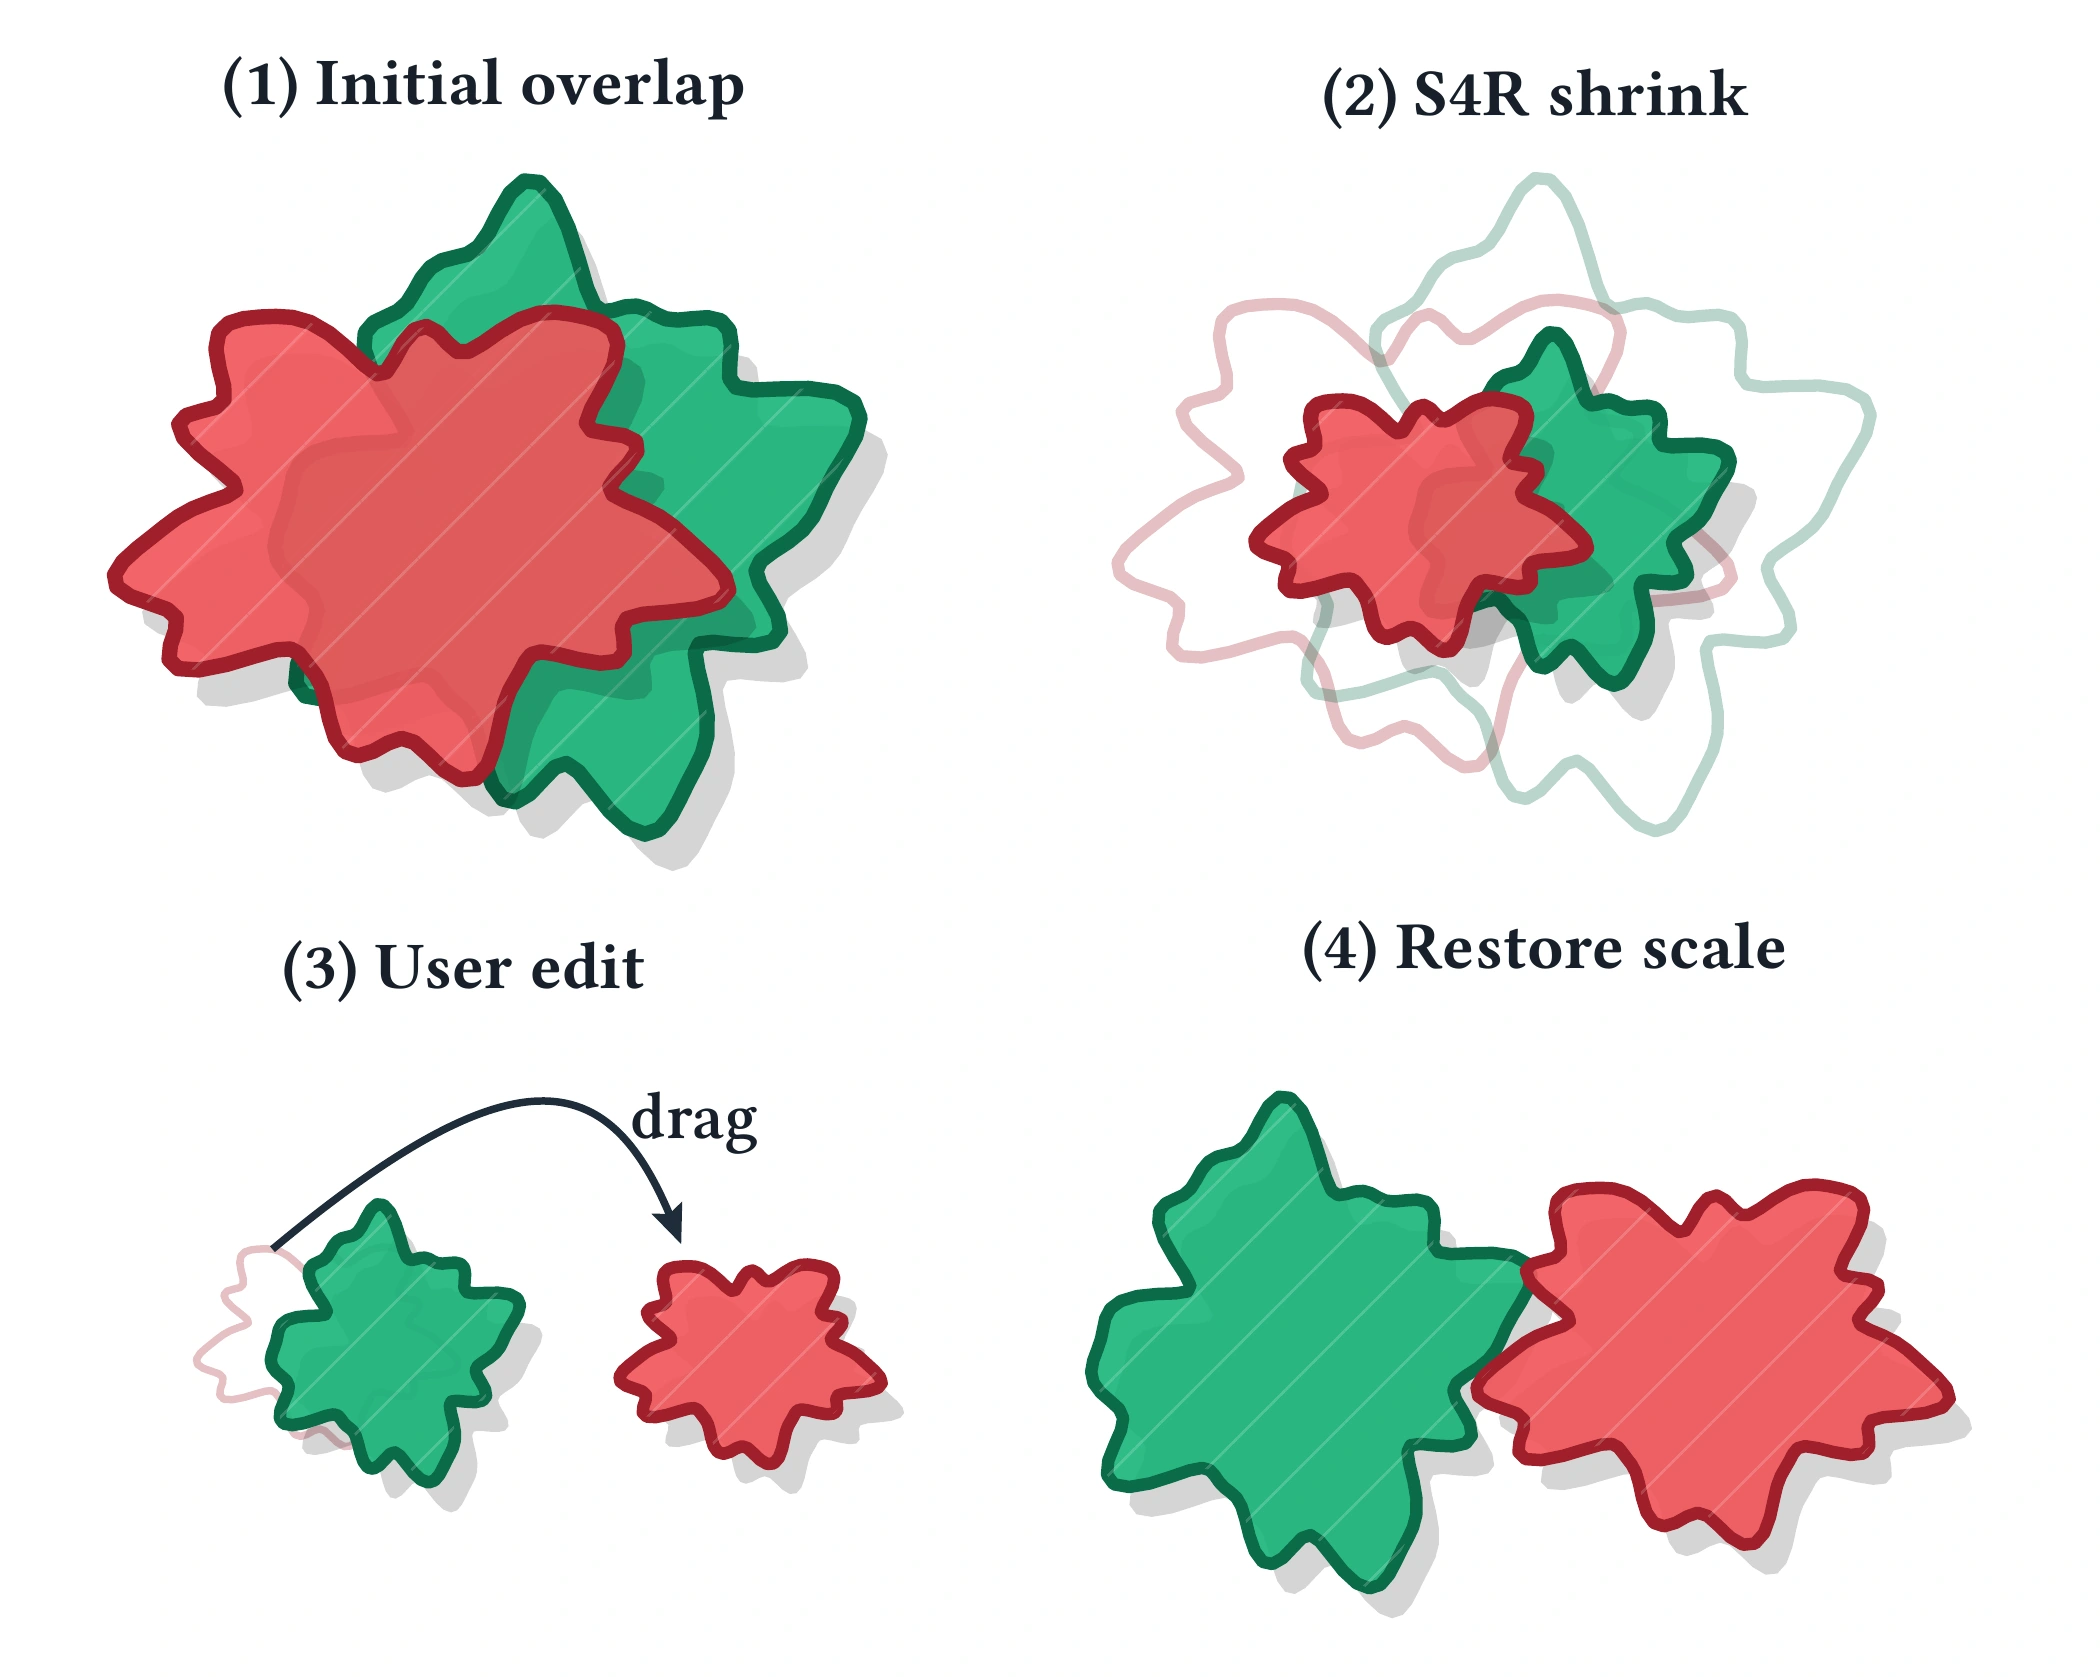
The separated small-scale state can also serve as an editing stage: a user rearranges the objects while they are apart, then lets S4R restore them to full scale.
Questions raised by readers, answered with additional experiments.
We thank Sarvex Jatasra for this question. S4R shrinks all objects and grows them back in small steps; each step moves the objects as little as possible while keeping them apart. Making every step small does not guarantee that the objects end up as close as possible to where they started. Would it help to also pull each object back toward its starting position?
We tested this by adding an anchor term α/2 ‖c + Δp − c0‖2 to each step, where c is an object's current position, Δp its move in this step, and c0 its starting position; each step remains a convex quadratic program. The pull can also move objects that touch nothing, so each step must additionally keep apart every pair that the pull could bring together. To tell the two changes apart, we also ran a control that uses these extra constraints without the pull.
Over 20 scenes per setting, all anchored runs end without overlaps. The anchor term alone reduces the final distance from the starting layout (RMSD) by 3–4% in every setting. The extra constraints alone increase it by about 4% in sparse scenes, which cancels the gain, but reduce it in dense piles. In a dense pile of 100 objects, the two together reduce the final RMSD by 12% at α = 1, at about four times the running time.
| Scenes | N | Anchor term alone | Extra constraints alone | Total |
|---|---|---|---|---|
| Kubric | 40 | −4.1 ± 1.3% | +3.6 ± 1.4% | −0.7 ± 1.1% |
| Kubric | 100 | −3.3 ± 0.6% | +3.9 ± 0.6% | +0.5 ± 0.9% |
| Spherical pile | 40 | −3.4 ± 1.2% | −2.4 ± 1.6% | −5.7 ± 1.7% |
| Spherical pile | 100 | −3.3 ± 0.8% | −9.2 ± 0.9% | −12.1 ± 0.8% |
Change in final RMSD at α = 1. Mean over 20 scenes ± 95% interval; negative means the objects end closer to their starting positions. Anchor term alone: anchored run vs. control. Extra constraints alone: control vs. default S4R. Total: anchored run vs. default S4R. All runs re-detect contacts at every step. Spherical piles place objects inside a ball, as in the spherical-spawn test of the paper.
@article{dou2026s4r,
  title     = {{S4R}: Scaling for Rigid-Body Interpenetration Resolution},
  author    = {Dou, Zhiyang and Zhao, Ang and Peng, Chen and Guo, Minghao
               and Wu, Haixu and Lin, Cheng and Liu, Yuan and Yao, Junfeng
               and Guo, Xiaohu and Wang, Wenping and Matusik, Wojciech},
  journal   = {ACM Transactions on Graphics},
  volume    = {45},
  number    = {6},
  articleno = {197},
  month     = dec,
  year      = {2026},
  doi       = {10.1145/3842510}
}